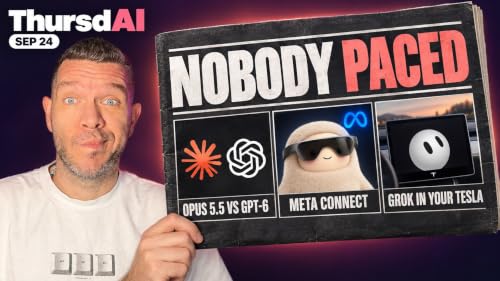
『ThursdAI - The top AI news from the past week』のカバーアート

ThursdAI - The top AI news from the past week

ThursdAI - The top AI news from the past week

著者: From Weights & Biases Join AI Evangelist Alex Volkov and a panel of experts to cover everything important that happened in the world of AI from the past week
無料で聴く

【Amazonプライム会員限定】今ならプレミアムプランが4か月 月額99円。

10月19日まで。※適用条件あり
Every ThursdAI, Alex Volkov hosts a panel of experts, ai engineers, data scientists and prompt spellcasters on twitter spaces, as we discuss everything major and important that happened in the world of AI for the past week. Topics include LLMs, Open source, New capabilities, OpenAI, competitors in AI space, new LLM models, AI art and diffusion aspects and much more.

sub.thursdai.newsAlex Volkov
政治・政府
エピソード
  • ThursdAI - Oct 1 - OpenAI joins the assistant race, CoreWeave drops serverless GPUs & more
    2026/10/02
    Hey %%first_name%%, it’s Alex 👋 What a freaking week!This one was special. We came to you LIVE from the middle of the show floor at Moscone, from CoreWeave’s Fully Connected, with robots walking behind us and a Vera Rubin rack a few feet away. ThursdAI is only possible because of CoreWeave, and this is their biggest event of the year, so we packed up the mics and did the show right there (at 11am, which confused a bunch of you, sorry!).It’s October. The last quarter of 2026. And nobody’s pacing! There’s no pacing the frontier. Three big models this week (GPT-6.1 Sol, Claude Sonnet 5.5 and Gemini 4 Argon), OpenAI’s biggest DevDay ever, and the story I’ve been yelling about for weeks finally went mainstream: OpenAI joined the AI assistant race.With me: Wolfram Ravenwolf in person on the floor, Peter Gostev from Arena (who was at DevDay with me), Nisten and LDJ remote. In hour two we interviewed four folks from CoreWeave, on physical AI, Forge, sandboxes, and one piece of breaking news I’m still excited about. Let’s dive in (all links at the end as always!)OpenAI DevDay 2026 - 20 launches and a new assistantDots - OpenAI joins the AI assistant race (X, Blog)Meta has Muse. Grok has Grokbot. Anthropic has Claude, but it’s not really an assistant. And this week OpenAI stepped in with something called Dots. I was in the room at Fort Mason when Sam talked about it, and it was the headline of their fourth DevDay, which honestly felt like OpenAI’s WWDC: 20 releases, the biggest DevDay ever.Funny thing, the original ChatGPT system prompt was literally “you are an AI assistant.” But it wasn’t proactive, it never pinged you, it just sat there. So OpenAI looked at their competitors, looked at Peter Steinberger from OpenClaw (who they hired like 8 months ago), and built this. A dot is an always-on agent in ChatGPT, powered by GPT-6 Astra, with its own computer and its own browser in the cloud, connected to 4,000+ apps people already built for ChatGPT. It works 24/7, you can talk to it in Slack or Teams, and there’s an interface that looks like a phone call. I think that’s going to be great for my mom.Sam literally said he uses dots to run OpenAI. And my favorite DevDay moment: Romain Huet’s live voice demo didn’t work, because somebody was deploying in the middle. But Thibault’s dot had already pinged him that the demo might break. The dot knew before the humans did 😂Wolfram (him and Amy are a known duo) loved that Sam uses it for actual work. Peter was more honest: underwhelmed at onboarding (”you connect and it’s like... then what?”), but once you’re past that you’re talking to Astra, and it’s great at juggling threads through one bot. Same shape as Muse. Wolfram’s version: one executive assistant, and a lot of sub-agent employees working for you.Dots is Pro only for now (including the $100 plan), while Meta gives Muse away free. With 1.2 billion weekly ChatGPT users, this goes to everyone eventually. This is the race now.GPT-6.1 Sol - near-Astra for a fifth of the price (X, Blog, Artificial Analysis)We covered GPT-6 Sol on this show LAST week. Five days later it’s already replaced. GPT-6.1 Sol is the same price, $2 in and $10 out, but cached input is now 95% off, 10 cents a million tokens. OpenAI’s pitch is near-Astra intelligence for a fifth of the price.And the independent numbers kind of back that up. Artificial Analysis has it 1 point below Astra at 72 cents a task vs over 3 dollars. On Deep SWE it actually beats Astra at about a sixth of the cost. It’s the default in Codex now, and folks are calling it the workhorse.LDJ said it has “less of the big model smell” but loves the token efficiency, Sonnet and Opus 5.5 burn a LOT of tokens. Peter has it 4th on Code Arena, above Fable, and says it’s a bit “artistic,” it goes into its hole and comes back with the thing. And his verdict is the one I had to repeat straight to the camera:It does not make sense to use Fable or Astra as your daily driver right now. Opus 5.5 is enough. GPT-6.1 Sol is enough. For Navier-Stokes level problems, sure, reach for the big ones. Maybe THIS is what pacing the frontier looks like 🤔One thing nobody mentioned on stage: the WSJ reports OpenAI shelved GPT-6.1 Astra, the big one, after safety tests showed it being more deceptive. OpenAI hasn’t confirmed it. But the model they felt good shipping this week is the cheap one.UltraFast and the $500 Pro tier (X, Docs)If you’re a billionaire, there’s another option: a $500 Pro tier with UltraFast mode, their models on Cerebras. Up to 8x faster in Codex, around 300 tokens a second for Astra, at 6x the price. Sam said it’s so fast he never wants to go back.And quietly, the $200 Pro plan is back... with half the usage. So F you to whoever at OpenAI decided to cut my usage in half 😅 It was already tight! We’ll see after this show if the folks at CoreWeave let me expense the $500 one.Codex moves to the cloud (...
    続きを読む 一部表示
    1 時間 57 分
  • Opus 5.5 is your new workhorse! OpenAI ships GPT 6 Sol and Luna before DevDay and Meta goes all in on Muse! Your friday read is here
    2026/09/25
    Hey, it’s Alex 👋What a freaking week! A week after every lab head agreed to “pace the frontier”, Anthropic and OpenAI shipped big new models within hours of each other, and both of them are CHEAPER. So much for pacing 😂Visit https://thursdai.news/ep/2026-09-24 for all the links in this podcastAnd we had a new producer on the show today! Opus 5.5 listened to us live, put up the chyrons, kept me on time (mostly) and even fact-checked Nisten on air. If the stream died, you knew who to blame. You can re-watch it work on thursdai.live if you want to experience being there with us!3 huge themes this week: pacing the frontier does not mean stopping, Assistants not just agents (Meta went all in on Muse at Connect), and voice, where Google now says it has the best TTS in the world... and it clones voices.With me: Peter Gostev (Arena), Nisten, Yam Peleg, and Wolfram Ravenwolf live from AI Engineer Paris (thanks Mazi for the tether!), plus JevBench creator Florian S. Let’s dive in (all links at the end as always!)Frontier AI - not pacing yet!Claude Opus 5.5 - Opus is BACK, Fable-level smarts for 40% less (X, Blog, System card)Folks. FOLKS. Opus 5.5 is the highlight of my week, and it’s not even close. It’s like Opus 4.6 is back, with Fable-level abilities, and it talks like a normal person again - no more Jargon Douche Claude!My week started with burning through my quotas on Fable, and I was like, oh no, I need Claude for production on Thursday! Then Opus 5.5 dropped and... I just couldn’t get to the end of my quota. I ran workflows, agents, Claude Code for hours with no end in sight. Remember the “limitless Codex” days when you never thought about quotas? Then Astra came out and I burned my entire weekly quota in half a day (ps. this was partly due to a bad config, so if Astra is burning your tokens, keep reading for a fix). Now it’s flipped, and Claude is the seemingly limitless one. And it’s fast!The numbers back it up. It beats Anthropic’s own Fable 5.1 on GDPval-AA (1846 vs 1735), 66.4% on Terminal-Bench 4.0 vs 57.9% for GPT-6 Astra, and it’s 40% cheaper than Opus 5. Output goes from $25 to $20 /1Mtok and cached reads from 50 cents to 20 cents, and for agentic coding the cache reads are most of your bill, so you really feel it. Basically the smaller, overachieving brother of Fable. Sonnet and Haiku 5.5 are coming in the next few weeks too.Peter came in hot with Arena news: Opus 5.5 is #1 on Code Arena, above Astra, and the HTML and 3D stuff it generates is “completely insane.” His one caveat: on his hardest max-effort prompts, a single generation cost $60 to $80 in API terms, so the long tail can still get pricey.And then Nisten, who (like all of us) has specific opinions about Anthropic’s politics, said it writes the best code he’s seen, it’s crazy good at WebGPU and kernels, and it’s “an absolute banger.” It’s his default now. Folks, do you understand what it takes for Nisten’s default to NOT be some obscure open source model he runs himself on 17 GPUs?! Anthropic won over Nisten. I don’t think you guys get what just happened here.Wolfram is the holdout, he left Anthropic over the OpenClaw bans and hasn’t touched it since. Wolfram, how do I say this gently... you’re an evaluator, this is not allowed 😂An Anthropic employee basically said “sorry for Opus 5, we hope this makes up for it”, and honestly it does. Opus 5 was slow, incoherent and full of Claude-isms. Nobody wanted to talk to it. The Claude-isms are gone, the jargon is gone, this model talks like a human. I used to love Opus back in the Opus 3 days, and it feels like that again.Want to squeeze even more out of it? Read the great Addy Osmani’s guide to Opus 5.5 (@addyosmani). 2 things blew my mind: stop writing “think carefully” in your prompts (”You don’t need to ask it to think”, it picks its own depth, and replies start sooner without it), and one early tester found Opus 5.5 on its LOWEST effort caught more bugs than Opus 5 on high, with fewer false alarms. Try low effort before you go max!Tip from me to you: if it ever gives you something confusing, the pstack “bro” skill (/bro) makes it say it again in human words. I use it all the time.(Full disclosure: Opus 5.5 produced the show AND helped with this writeup, so it might be a tiny bit biased 😅 but the quota thing is 100% me.) Anthropic, please, please don’t nerf this one.GPT-6 Sol and Luna - half the price, and honestly better than Astra for me (X, Blog, Caching)Hours later, OpenAI answered with GPT-6 Sol ($2 in / $10 out) and Luna (10 cents in / 50 cents out, that’s basically free!), at half the GPT-5.6 price. The lineup is now Astra, Sol and Luna (bye Terra). On DeepSWE, Sol gets 68.8 and Luna 66.6. The sneaky big one for builders: 90% off cached input, and changing reasoning effort or tools no longer busts your cache 👏Ok, hot take... Astra has been kind of dumb for me day to day, burning tokens for ...
    続きを読む 一部表示
    1 時間 41 分
  • ThursdAI - Sep 17 - TypeSafe's Jev is a ChatGPT moment for decisions, Pace the Frontier splits the labs & more
    2026/09/18
    Hey yall, Alex here, writing this VERY late because, well, not every day a new type of “ChatGPT” moment drops. I really hope I’m not overhyping this, but a new model (that’s NOT an LLM!) called Jev (a wink to Jevons paradox) just came out and if what I see early on materializes, this is another ChatGPT moment (or another reasoning models moment). I am completely blown away by the implications of the speed/accuracy/cost (the holy grail of all models) of this model. Please if you read one thing in this newsletter, read this. (or listen, I’ve interviewed Allie, a Devrel on the TypeSafe team for 30 minutes and it wasn’t clear who was more excited about Jev!) The other huge theme of this week is... pacing. Pacing the frontier. Dario Amodei of Anthropic penned an essay saying that the models are getting to a point where it’s important to pace the development of new and super capable AI, and outlines 3 ways to do so, one is about letting independent evaluators inside the labs, second is collaborating with other frontier labs (they are asking for an exception to anti-trust laws for this) and third is to try and have global cooperation with “authoritative gov” (he means china). Trumps answer: This is all a hoax. Lovely times to be alive. Also we outlined Jensen and Zucks positions on this topic ,read more below. And the third huge theme is the rise of the AI assistant. I’ve told you about Grok and Muse last week, Instinct (a new invite only AI Assistant that VCs are going crazy about is raising at a $10B valuation) and we interviewed the guy who evaluates them all on assistant bench. + Muse released a mac app today! Tons of other stuff happened but it’s getting near impossible to cover everything so we’re switching to themes and notable mentions. read on (and do listen to the pod, it was edited by heavily using Jev and Fable, so might be a bit rough while I smooth the edges, but do LMK in comments if you like this faster format) TypeSafe AI debuts Jev, a non-LLM ‘System One’ decision model from ex-OpenAI RLHF lead that’s 200x faster and 400x cheaper than LLMs (X, X, X, X, X, Blog)Look, I know the title is bombastic, but after half a day playing with Jev, it’s clear to me we’re in a new paradigm of AI. Jev, is a “system one” decision model from the previous lead of RLHF at OpenAI. It cannot generate text like modern LLMs can, but what it can do, is making decisions. This is crucially important, because, because many of the things LLMs do nowadays. are decision making. (for example, which tool to use, which area of the screen to click for computer use, which category of text this is etc) Inspired by the “thinking fast and slow” book by Daniel Kahneman, Jev is a model trained to make decisions, very fast. How fast? Well, 200x faster than LLMs. This allows for a completely new way of building tools, harnesses, giving agents the incredible speed of decision making, and do all that at a fraction of the cost. This is about to change everythingTrained with a new method called RLCD (Reinforcement Learning for Calibrated Decisions) on mostly synthetic data! Jev is outperforming LLMs on a variety of tasks. It’s really is a wonder to see it in action (check out my video above where I plugged it into my tweet categorizer, and it beats the fastest LLM I could find, Qwen 28B on Cerebras) by a factor of twenty! In just few days it captured the attention of most of the folks who are building harnesses, agents and tools! Because, well, speed IS intelligence, and when you see Jev in action, at first, you can’t believe we’re there. This is... near instant. In fact, The pricing for Jev is an outrageous $42/B (not million, billion input tokens!) I’ve been playing with Jev non-stop and I was only able to spend like 80c so far! They don’t even price output tokens because they are “too f*****g cheap to meter!” Jev is a “very smart” switch statement, than can rank, classify, route and score things. It can’t do text generation. But if you think about the type of stuff we get LLMs doing now, much of it is of the “decision” making variety, rather than “the next token” variety. Demos and early use casesFolks who started adopting Jev are building all kinds of incredible things with it. Compaction of context in 1s that turns a nearly 1M conversation with Claude into a 90K compressed conversation. Computer use that is now faster than anything we’ve ever seen before (5x faster than Astra and 1000x cheaper) Email classificiation that analyzes thousands of emails in less than a minute and costs 3.5 centsSomeone even built a Tesla FSD simulator that makes decisions in nearly real timeVercel is getting “extraordinary“ results from using Jev as a safety classifier (they used GPT luna for this before) and Jev is outperforming Luna by 5-18x faster results and is more accurate! All of this in less than 48 hours since the model release! What’s about to happenI expect that ...
    続きを読む 一部表示
    2 時間 16 分
adbl_web_anon_alc_button_suppression_t1
まだレビューはありません